Familiar Julia code, multiple GPUs
Large scientific calculations often need more memory and compute than a single GPU can provide. Scaling them asks researchers to manage data partitioning, communication, and hardware details alongside their science. cuNumeric.jl lets them express supported calculations using familiar array operations while the runtime automatically partitions and distributes the work across GPUs.
Built on NVIDIA’s cuPyNumeric, cuNumeric.jl combines Julia’s ability to reuse generic algorithms with automatic management of data movement and parallel execution. Our latest work shows how this approach can scale existing scientific solvers and deliver competitive performance without asking users to write GPU kernels or communication code.
The results below are from our manuscript under review, evaluated on one to eight NVIDIA H200 GPUs in a single node. The plots are also available in the cuNumeric.jl benchmark documentation.
Reusing existing scientific libraries
Our NDArray type implements Julia’s AbstractArray interface. When an existing algorithm calls
operations such as matrix multiplication or a reduction, Julia dispatches to the implementations for
that array type. This lets a solver use our multi-GPU backend without changing the solver’s source
code.
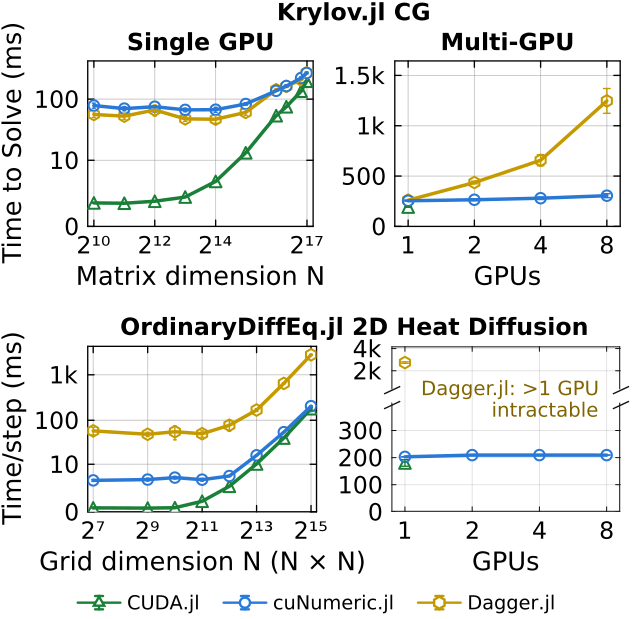
We demonstrated this by solving a linear system with Krylov.jl and solving the 2D heat diffusion equation with time-stepping algorithms from OrdinaryDiffEq.jl. Neither library required source changes. At eight GPUs, the two examples retained 84% and 97% weak-scaling efficiency, respectively, relative to the single-GPU baselines. Weak scaling grows the problem with the GPU count while keeping the work per GPU constant. At the largest tested single-GPU sizes, execution times were within 36% of CUDA.jl for Krylov.jl and 13.6% for OrdinaryDiffEq.jl showing that the overhead of the runtime is amortized when the problem size is large enough.
Making array programs efficient
Executing every array operation separately creates many small GPU kernels, temporary arrays, and unnecessary synchronization. We address these costs with macro metaprogramming, without modifying Julia’s compiler or the distributed runtime.
Broadcast fusion combines supported elementwise expressions into a single kernel:
# One fused computation, distributed across GPUs
result .= a .* x .+ b .* y
For larger regions of code, our @accelerate macro fuses eligible operations across expression
boundaries, including independent expressions that share inputs. It also identifies when temporary
arrays are no longer needed so their storage can be reclaimed or reused. This matters because GPU
allocations managed outside Julia are not fully reflected in its garbage collector’s memory pressure
estimates.
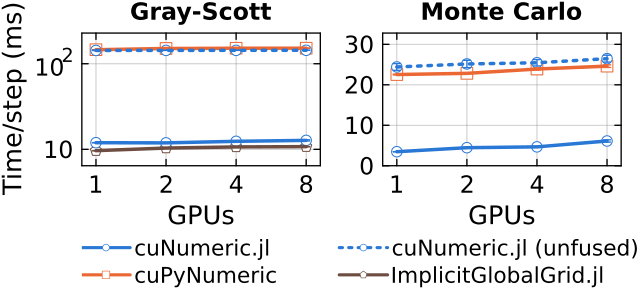
In our Gray–Scott reaction–diffusion experiment, fusion improved performance by roughly an order of magnitude relative to unfused execution across one to eight GPUs. The fused array code achieved performance competitive with ImplicitGlobalGrid.jl, a specialized stencil library that uses custom halo-exchange kernels and MPI to communicate between GPUs.
Performance and code complexity
We evaluated seven additional workloads: NAS FT, EP, and MG; HPC-CG, Gray–Scott, Monte Carlo integration, and dense matrix multiplication (GEMM).
- 5.8× geometric-mean speedup over cuPyNumeric, the Python array library used as our backend baseline, and 2.4× over Dagger.jl across the benchmark suite and one-to-eight-GPU weak scaling.
- Performance matching JACC.jl on average, while retaining the higher-level array interface. This comparison excludes GEMM because JACC.jl lacks the required matrix–matrix operation.
- 45% lower average cyclomatic complexity than Dagger.jl and 54% lower than JACC.jl in the benchmark implementations. This measure counts independent control-flow paths; our code’s complexity was comparable to single-GPU CUDA.jl.
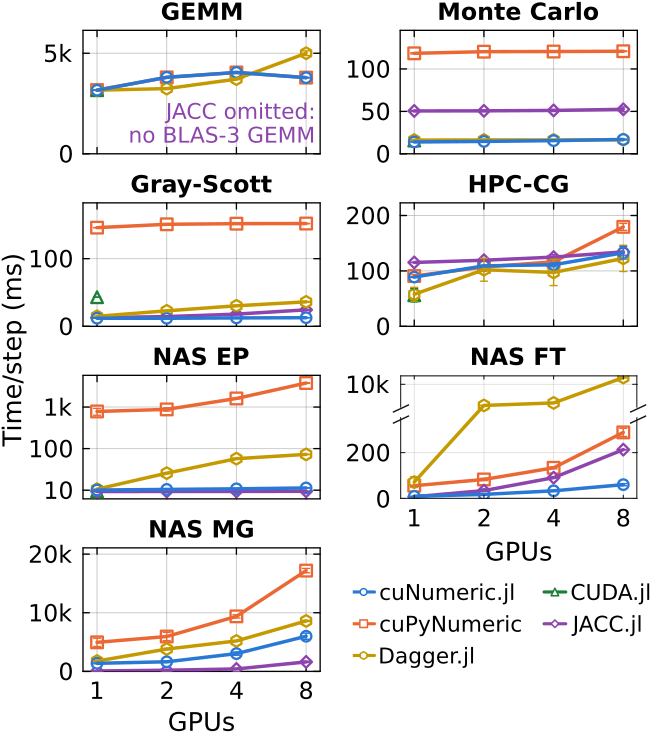
Timings measure steady-state execution after warm-up, with inputs already on the GPUs, and average five trials. They exclude compilation and other cold-start costs. Larger workloads amortize the distributed runtime’s overhead; CUDA.jl remains substantially faster for small problems. Multi-node execution is experimental and was not evaluated in this study.
Project background and my contribution
I originated the project and co-develop it with fellow DOE CSGF recipient David Krasowska. We approached NVIDIA at the 2024 Supercomputing conference and have met with them weekly since then.
I primarily focus on the user-facing API and Julia implementation, including automatic broadcast fusion. David focuses more on the underlying Legate runtime and memory management.
Talks & podcast
I served as a local liaison for JuliaCon 2025 in Pittsburgh, helping with setup and coordinating spaces and reservations with CMU and the University of Pittsburgh. David and I presented cuNumeric.jl: Automating Distributed Numerical Computing, covering a very early version of the project, before the work and results in the current manuscript. Watch the early talk.
On Science in Parallel, David and I discuss how we started cuNumeric.jl and our collaboration with NVIDIA. Listen to the episode.
JuliaCon 2025: an early version
I served as a local liaison for JuliaCon 2025 in Pittsburgh and presented my talk with David Krasowska, “cuNumeric.jl: Automating Distributed Numerical Computing.” This talk presents a very early version of the project and predates the work and benchmark results in our manuscript under review.